← All skills

Skill

Data-oriented design

Organizing a program around how its data is laid out and accessed. Achilles stores every field as a structure of arrays, with passes that declare what they read and write.

2 log entries1 project

AchillesBest example

V3: designing for performance

Commit

Also shows: C++Performance & SIMD

For V3, I wrote a full design document before writing any code. The target was concrete: simulate my club's six-robot arena of holonomic turret robots fast enough to train RL policies on a laptop CPU, since we don't have much GPU compute. Training takes millions of steps, so throughput was the goal, and V3 doubled as a performance learning exercise. One rule drove most decisions: only costs paid every frame matter. Only joint state, plus the contact solver's last solution, persists between frames. Everything else is either static data built at load time or scratch memory rebuilt each step and reused between passes. That rule became three pieces: fields; small operations that declare exactly which fields they read and write; and traversals that apply those operations across the joint tree, all checked at compile time. What the compiler can't check, the engine checks as it starts, and CI runs death tests confirming that a bad setup, like a model that doesn't fit its layout or an overflowing arena, stops it with a clear message instead of quietly corrupting a run. I kept V2's physically meaningful types but moved them into the math rather than the structure, so adding collisions or rendering meant adding passes instead of rewiring classes.
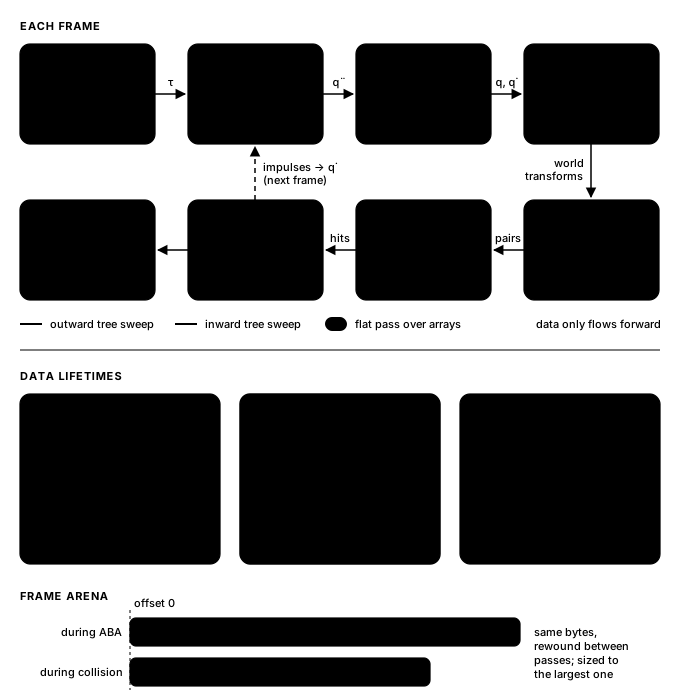
The V3 design: each frame runs eight passes in one direction (actuator torques, ABA forward dynamics, integration, kinematics, then broad phase, narrow phase, contact resolution and a debug render), and below it, which data is static, which persists between frames, and which is rebuilt each frame in a reused arena
V3 as designed. Collisions changed once I built them (see above).

Achilles

SIMD: eight robots per instruction

Pull request

Also shows: Performance & SIMDC++

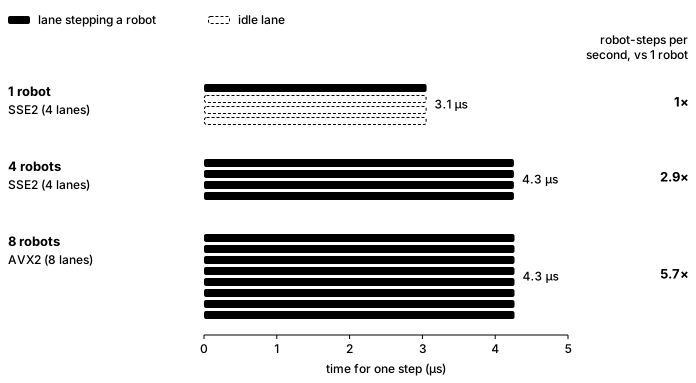
V3 replaces V2's Eigen with my own spatial algebra on xsimd, and stores every field as a structure of arrays: each component of each field, say the x angular velocity of every joint, is its own contiguous, aligned array. Joints are sorted by their depth in the tree, and each group of SIMD lanes holds joints at the same depth. With many copies of one robot, that puts the same joint of different robots side by side, so one instruction can load, update or store a quantity for eight robots at once (eight lanes with AVX2, four in the default SSE2 build). A Valgrind trace of the compiled binary confirms it: 88.9% of all accesses to simulation data are whole, aligned 8-lane vector loads or stores. The payoff is that filling the lanes is nearly free. On a seven-link arm, one robot takes 3.1 µs per step, while eight robots in the 8-lane build take 4.3 µs, 5.7× the robot-steps per second.

Three bars of SIMD lanes showing the time for one step of a seven-link arm: one robot in the 4-lane build takes 3.1 microseconds with three lanes idle; four robots fill the lanes in 4.3 microseconds, 2.9 times the robot-steps per second; eight robots in the 8-lane AVX2 build take 4.3 microseconds, 5.7 times
One step of a seven-link arm on one CPU core, best of 18 runs. Batched runs also step one shared fixed root.
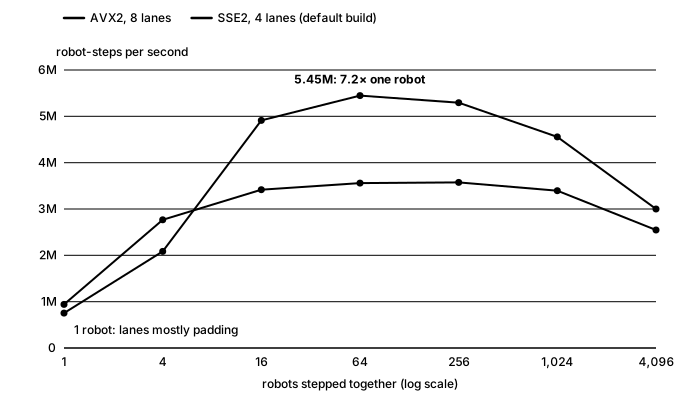
Line chart of robot-steps per second against robots stepped together, seven-link arm. With one robot, 8-lane AVX2 does 0.75 million and 4-lane SSE 0.94 million. AVX2 climbs to 5.45 million at 64 robots, 7.2 times its one-robot rate; SSE levels off near 3.6 million.
The same effect across batch sizes: throughput climbs until the lanes are full.