Benchmarking VLAs for ARCHITECTBest example
The paper: A Few Words Go a Long Way
- Hardware
- Franka Panda
- Role
- Co-author
- Status
- On arXiv
Also shows: Robot learning
ARCHITECT is the lab's system, not mine: I'm a co-author for the VLA benchmark behind its comparison. The paper asks whether robot programs written by a coding agent, and fixed with a few words from a person, can beat end-to-end VLAs. ARCHITECT has an LLM write a program from perception and control tools, runs it, and reads back an execution trace. When it fails, a person says what went wrong ("grasp the cup from the top"), and the fix is saved to a skill library the agent reuses on later tasks.
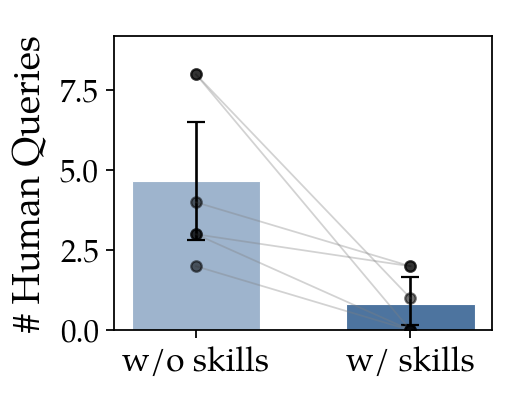
On eight real tasks on a Franka Panda, ARCHITECT succeeded 70 to 100% of the time on every one, while Code as Policies, which writes the program once, topped out at 60%. The VLAs held their own only on simple pick and place, where π0.5 succeeded 90% of the time on the banana and every time on the block, against ARCHITECT's 80% and 70%; they scored 0 to 10% on the drawer, the cloth and the hidden banana. A six-person study tested the skill library: with skills learned on the cup task, people needed 0.83 corrections per trial on the box task instead of 4.67, and with no corrections at all, success on the box task went from 0 of 6 to 4 of 6.