← All skills

Skill

Experiment design

Setting up measurements so the answer can be trusted. The Odin localization campaign against motion capture, its error model, and the VLA benchmark's fair-test design.

3 log entries2 projects

Advanced Robotics at UWBest example

An error model for the Odin

Analysis code

Also shows: State estimationPython

The question wasn't how accurate the Odin is but whether the sentry could rely on it alone, and one accuracy number can't answer that: the nav stack needs to know how the error behaves, whether it grows, and what happens when something goes wrong. So I designed the October 3 campaign around those questions (figure-8 laps, a long hold, repeated relocalizations and covered-sensor trials, all against mocap) and fit a small model to it: the true pose, plus an offset drawn each time the Odin relocalizes into its map, plus first-order Gauss-Markov noise: correlated over time, but decaying.

poseout(t)=posetrue(t−τd)⊕ε(t),τd≈0
ε(t)=R(ψ)Tbk+η(t)
bk∼N(0, diag(σb2)),per relocalizationk
ηi[n+1]=aiηi[n]+σi1−ai2wi[n]
ai=e−Δt/τc,i,Δt=0.1s

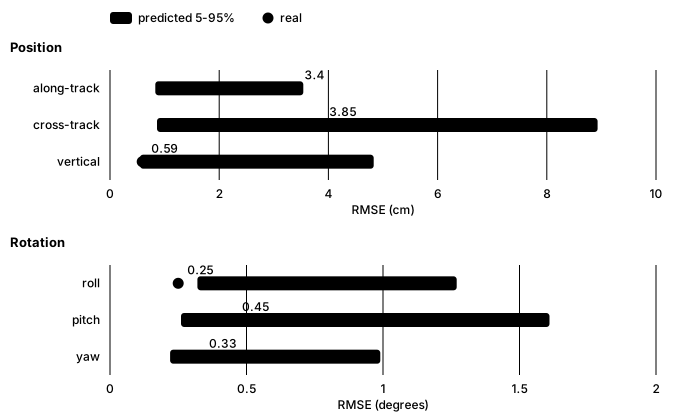
Splitting the error this way was the key decision. The offset from each relocalization turned out to be the largest term, which one overall noise figure would have blurred, and modelling the noise as decaying showed the error stays bounded instead of drifting. To check the model wasn't just describing the data it was fit to, I refit it without one session, simulated it many times along that session's real path (a Monte Carlo check), and asked whether the real error fell where the simulations said it would. It did: its real error there, 5.1 cm horizontal and under half a degree, matched the prediction on all six axes (roll came in just under its predicted range, still within the test). That made the recommendation clear: the Odin can be the sentry's only localization, kept on the turret major, where it swivels independently of the turret and the chassis. We tried it in several mount locations and found the occlusions made little difference. The nav stack only has to handle a rare wrong relocalization, and the output pausing while the sensor is covered.
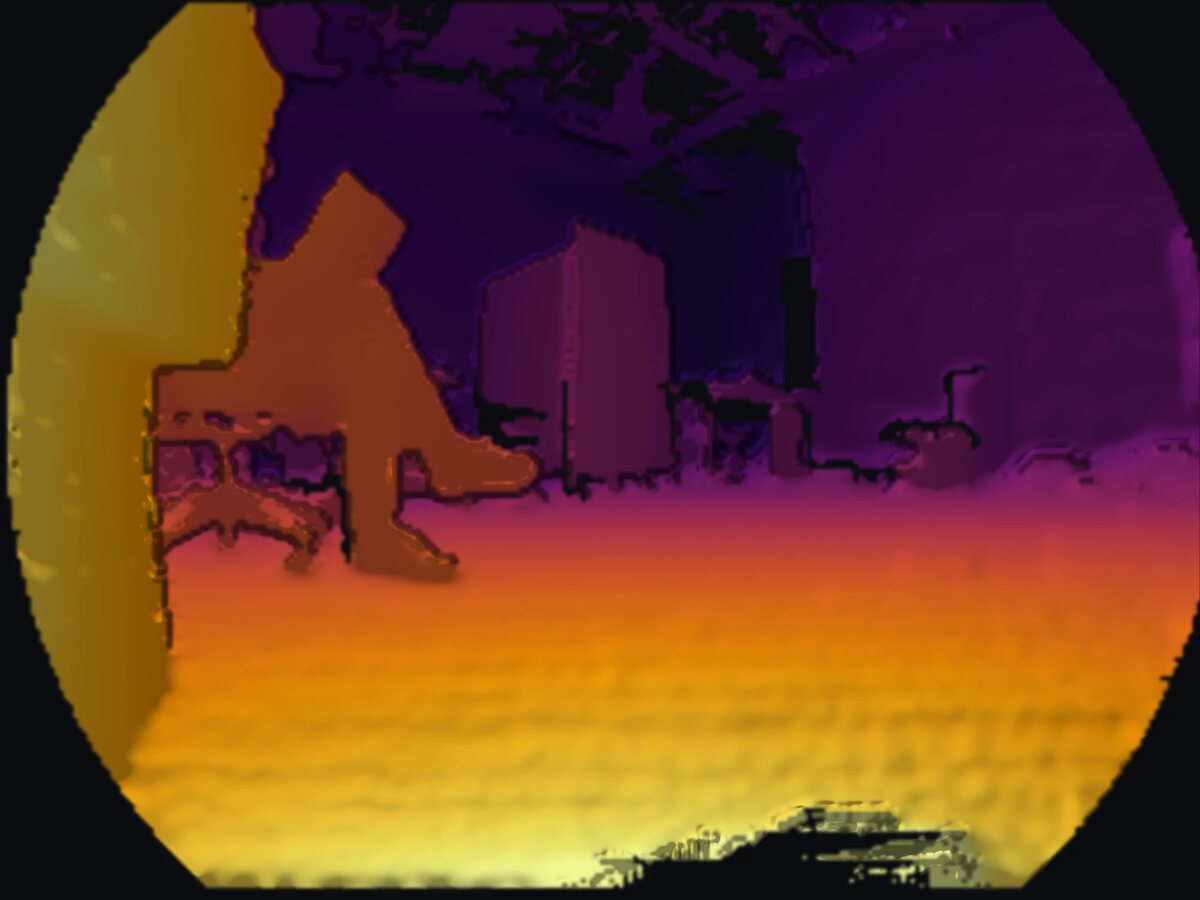
Depth image from the Odin, colored from yellow for near to purple for far, in its round fisheye frame: a wall close by on the left, a person sitting in a chair, and boxes and furniture across the room
What the Odin sees: a depth image from its recordings, near in yellow and far in purple.
Chart: for each axis, the Odin's real error on a held-out session as a dot against the model's predicted range as a bar; along-track, cross-track and vertical position, and roll, pitch and yaw
The hold-out check: the model, refitted without one session, predicts that session's error. Every axis passes; roll comes in just under its predicted range.

Advanced Robotics at UW

A test platform against motion capture

Code

Also shows: Python

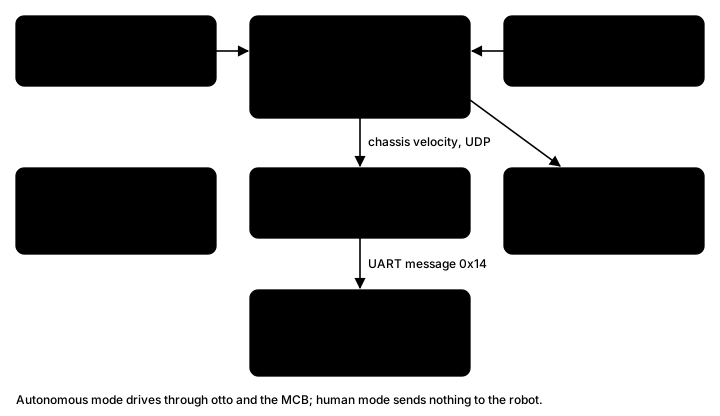
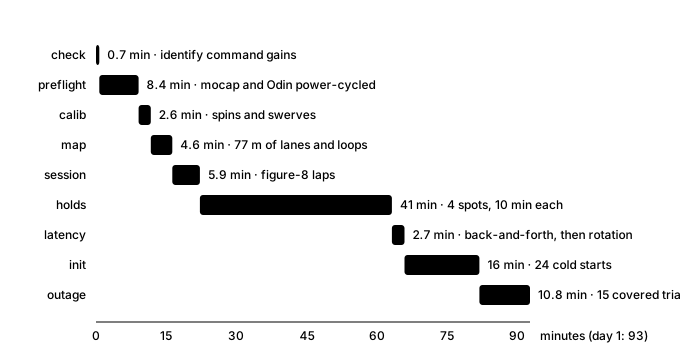
The sentry localizes with an Odin1, a lidar-inertial sensor that relocalizes into a prebuilt map. Before the team decided whether the whole localization system could rely on it alone, we wanted to know how accurate it is and where it is weak. So I built a test platform that measures it against the motion capture room, whose OptiTrack tracks the robot to a fraction of a millimeter. It starts and stops the sensor, records every run, guides whoever is driving with live mocap feedback, and can also drive the robot itself through the Jetson and the robot's controller, with a watchdog and speed caps. A campaign day runs a fixed protocol: calibration spins, a mapping drive, figure-8 laps at set speeds, ten-minute holds, back-and-forth motion to measure latency, cold starts, and outages where someone covers the sensor.

Diagram of the system: motion capture and the Odin1 sensor feed the characterization scripts, which record every run and write a report; in autonomous mode they send chassis velocities over UDP to the Jetson, which forwards them over UART to the sentry's motor control board
The three parts, and the default human-driven mode.
Bar timeline of day 1: preflight 8 minutes, calibration 3, mapping 5, figure-8 laps 6, holds 41, latency 3, cold starts 16, outages 11; 93 minutes in all
Day 1, step by step, from the campaign's time estimate.

Benchmarking VLAs for ARCHITECT

Designing the benchmark: what makes a VLA test fair

Task configs

Also shows: Robot learning

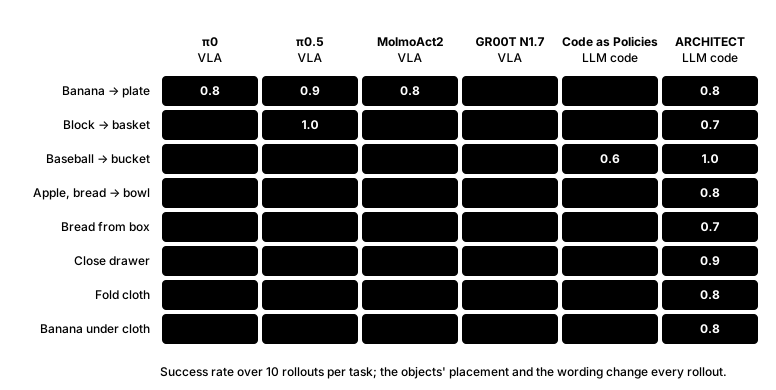
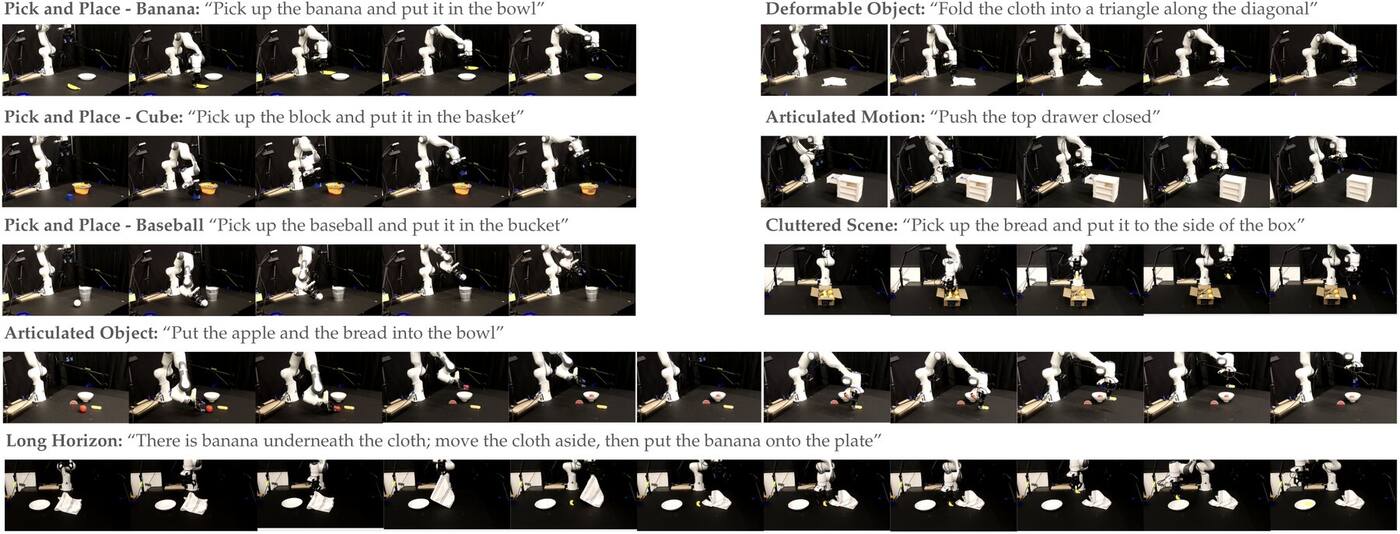
A VLA can look great near its training setup and fall apart a few centimeters away, so the hard part is deciding what a fair test is. We picked eight tasks across six kinds of challenge and changed the objects' placement and the wording on each of ten rollouts. We randomized the placements within a set workspace before running any evaluation, and every method ran the same ones. If I ran it again, the biggest thing I'd change is the lighting: we didn't control it well, and the models performed noticeably differently early in the morning than late at night.

Grid of success rates for eight tasks and six methods. The four VLAs score well only on simple pick and place, led by π0.5 at 0.9 and 1.0, and near zero on the drawer, the cloth fold and the banana under a cloth. Code as Policies peaks at 0.6. ARCHITECT scores 0.7 to 1.0 on every task
Success rate over 10 rollouts per task, from the paper's Tables 1 and 2.
Filmstrips of the eight evaluation tasks on the Franka, each labeled with its challenge and instruction: three pick and place tasks, a two-object pick and place, picking bread from a cluttered box, closing a drawer, folding a cloth and uncovering a banana
The eight tasks, from the paper's Figure 3.

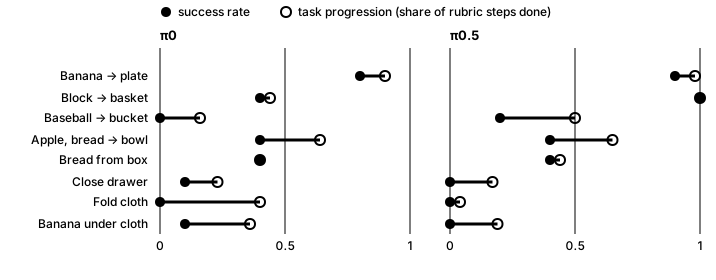
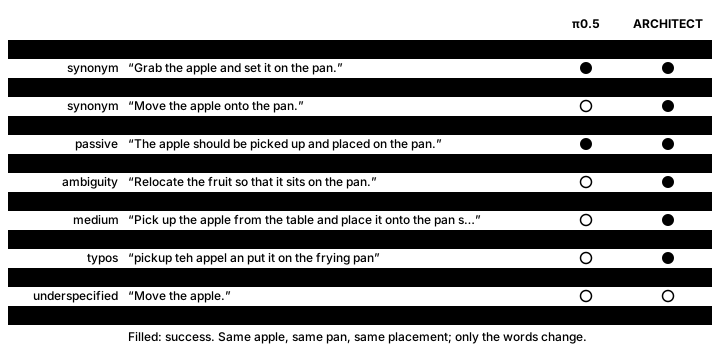
Success alone also hides a lot, so in the main benchmark each rollout was scored three ways: did it succeed, what fraction of the goals were met, and how far along a written rubric it got. Separately from that benchmark, we ran an ablation on wording alone: one task with the apple held still and only the instruction changed, fifteen phrasings run once each. π0.5 succeeded on "Grab the apple and set it on the pan" and failed on "Take the apple and place it onto the pan." It was sensitive to how specific the prompt was: given an underspecified one like "Put the apple away," the arm wandered without targeting the apple before eventually turning to the task, and an overly specified prompt degraded it the same way. It struggles when the task's intent is missing or buried.

MolmoAct2 was strong on the banana but struggled with the other pick-and-place tasks, which suggests it's fragile to object type, and on the harder tasks it often misread the prompt entirely, pressing the top of the cabinet instead of closing the drawer. It also disengaged early: in the two-object task it moved one object and withdrew, and in the cluttered box it picked the wrong object and never came back for the right one. Across all of it, the VLAs failed in the same few ways: sensitivity to how the prompt was worded, dependence on the object (π0 never got the baseball into the bucket), and poor spatial reasoning. They ignored vertical clearance, like the height of a barrier or how high to lift a cloth before setting it aside, and when a task called for a specific procedure they defaulted to another one that couldn't finish it, grabbing the drawer's lip instead of pushing it closed.

For π0 and π0.5 on each task, success rate beside task progression. On the hard tasks success is 0 to 0.1 while progression is often higher, such as π0 reaching 0.40 of the cloth fold
Why one number isn't enough: success against how far the policy got.
Fifteen phrasings of the same apple-to-pan instruction, with π0.5 and ARCHITECT marked for each. π0.5 succeeds on 6, failing on synonyms, reordered and ambiguous wording, typos and under- or over-specified instructions. ARCHITECT succeeds on 13
The language ablation: one task, fifteen phrasings, each run once.